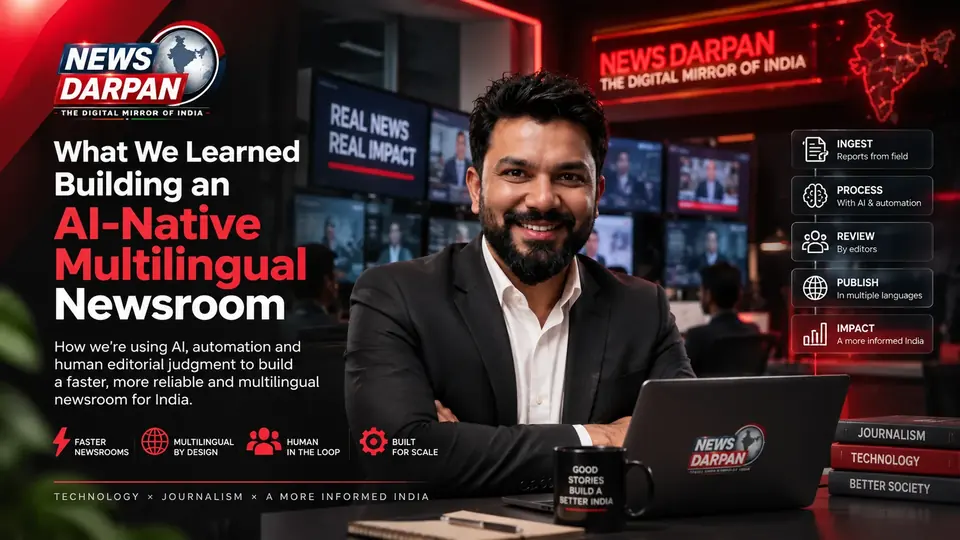
What We Learned Building an AI-Native Multilingual Newsroom
How News Darpan treats repetitive newsroom production work as software infrastructure, while keeping reporting, verification and editorial accountability under human control.
From field input to structured stories
Reporters don't normally work with structured databases. They send information through the tools they already use, including messaging platforms, web interfaces and staff applications. A report may contain text, photographs, video and additional context. Our first engineering problem is therefore ingestion. The system takes these different inputs and turns them into a structured representation of a potential story.Ingestion pipeline
A reporter's submission carries text, images, video and context. Ingestion turns those inputs into one structured story:
- Reporter: submits text, images, video and context
- Ingestion: parses the submission
- Structured Story: a machine-readable representation
We don't treat an LLM as the newsroom
One of the early lessons was that sending an entire story to one large language model and asking it to "write the news" is not a useful architecture. Different newsroom tasks have different requirements. A story may require research assistance, rewriting, translation, headline generation, summaries, SEO metadata, media processing and distribution. We therefore treat these as separate stages.Processing stages
One structured story fans out into independent stages, each with its own requirements:
- Research: supporting context
- Rewrite: editorial prose
- Translation: other languages
- Headlines: headline generation
- Metadata: SEO fields and schema
- Media: image and video processing
- Distribution: publishing and syndication
Human editorial control remains a hard requirement
For a news system, generation and verification cannot be treated as the same operation. An AI model can produce a convincing sentence even when the underlying information is incomplete or incorrect. So News Darpan keeps editorial approval as an explicit part of the workflow. A simplified version is:Editorial workflow
Generation and verification are separate operations, so approval is an explicit step rather than a side effect:
- Reporter
- Story Ingestion
- AI Processing
- Draft
- Quality Checks
- Editorial Review: can send the story back for review or correction
- Approval
- Publication
Reliability becomes part of editorial engineering
Once AI becomes part of a production system, prompt quality is only one part of the problem. Production systems also have to deal with failures. What happens when an AI request fails? What happens when an approved story gets stuck in a queue? What happens when an image is missing? What happens when metadata isn't generated? What happens when content becomes too old to publish automatically? These are software reliability problems, but in a newsroom they also become editorial problems. The system therefore includes background processes for tasks such as:- source polling
- approved-queue recovery
- SEO maintenance
- stale-content validation
- missing-image recovery
- classification
- audit notes
- primary-source references
- image attribution
- alt text
- responsive media
- backup operations
- storage monitoring
- pre-publication quality checks
- audit trails
Freshness is part of the data model
News is unusual because information can lose relevance simply through the passage of time. We don't want every piece of content to have the same freshness policy. Breaking news, general news and explainers can have different freshness requirements. That means the workflow can reason about content age before allowing certain automated operations. Conceptually:Freshness check
Content age is evaluated before any automated publishing step runs:
- Content
- Content Type: breaking news, general news or explainer
- Freshness Check: applies that type's policy
The check has two outcomes:
- Current: continue to publication
- Stale: route to review, or reject
Multilingual publishing is more than translation
India makes multilingual publishing particularly interesting. A newsroom serving multiple Indian languages cannot simply treat translation as a final step after an English article has been written. Different languages have different terminology, sentence structures and editorial conventions. We therefore think about multilingual publishing around the underlying story rather than around a single finished article.Publishing formats from one story context
The story context, not a finished English article, is the shared source for every output:
- Hindi
- English
- Regional Language
- Short Summary
- Social Format
- Video Format
The newsroom starts looking like a compiler
One useful mental model for the architecture is a compiler. A reporter provides a high-level input. The system parses that input into structured information. Different processing stages transform the representation. Editorial review acts as a gate. The approved story is then compiled into different publishing formats.The newsroom as a compiler
Raw reporting is parsed into a structured story, which is then compiled into each publishing format:
- Raw Reporting: the reporter's high-level input
- Structured Story: the parsed representation
From there the story compiles into:
- Article
- Translation
- Headline
- Summary
- SEO
- Social
- Video
All of which feed Distribution.
This model also makes traceability important. We want to understand where information entered the system, what transformations were performed, and where human approval occurred. For journalism, that matters as much as generation quality.What we deliberately don't automate
There are some decisions we don't want to turn into autonomous model decisions. We don't want a model to decide that a source is trustworthy simply because the model says it is. We don't want an algorithm to determine truth. We don't want automation to remove editorial accountability. And we don't want publishing speed to become an excuse for publishing unverified information. The interesting engineering question is therefore not: How do we make AI publish news without humans? It is: How much repetitive newsroom work can software remove while making human editorial control stronger rather than weaker? That's the problem we're building around with News Darpan.What we're building toward
News Darpan is being developed by Neelverse Studios around the idea that AI can become infrastructure for information-intensive organizations. Newsrooms are an unusually demanding environment because they combine:- unstructured inputs
- rapidly changing information
- multilingual content
- human judgement
- media processing
- publishing
- distribution
- auditability
- reliability
Frequently asked questions
What is News Darpan?
News Darpan is an AI-native newsroom system designed to treat repetitive production work as software infrastructure. It takes unstructured information from reporters (text, images, video, messages) and transforms it into structured stories while keeping reporting, verification, and editorial accountability under human control.
How does News Darpan handle information from reporters?
Reporters submit information through existing tools like messaging platforms, web interfaces, and staff applications. The system's ingestion stage takes these diverse inputs, text, photographs, video, and context, and converts them into a structured representation of a potential story.
What processing stages does News Darpan apply to stories?
Rather than sending an entire story to a single language model, News Darpan breaks newsroom tasks into separate stages: research assistance, rewriting, translation, headline generation, summaries, SEO metadata, media processing, and distribution.
How does News Darpan ensure editorial accuracy?
Editorial approval is an explicit part of the workflow. After AI processing and quality checks, human editors review and approve stories before publication. This separation ensures that generation and verification are distinct operations, preventing AI from publishing incomplete or incorrect information.
You may also like
 Politics
Dilip Tiwari Takes Charge As News Darpan Editor-in-Chief
 International
US and China seek stability amid race for AI and semiconductor dominance
 International
US and China should establish AI safety standards like nuclear-era safeguards, says lawmaker
 Technology
KL Deemed University partners with HCL to launch agentic AI campus for students
Most read
- 1
Tesla audits Chinese suppliers to scale up Optimus robot production
- 2
Former minister Lakhan Singh Rajput to inaugurate temple bhandara at Shri Chakreshwar Mahadev
- 3
Firozabad BSA finds four government schools locked during inspection
- 4
Tamil Nadu dengue cases fall for third consecutive year to 17,049
- 5
Social workers stage silent protest at Fufund railway station for train halts
Comments
No comments yet. Be the first to comment.